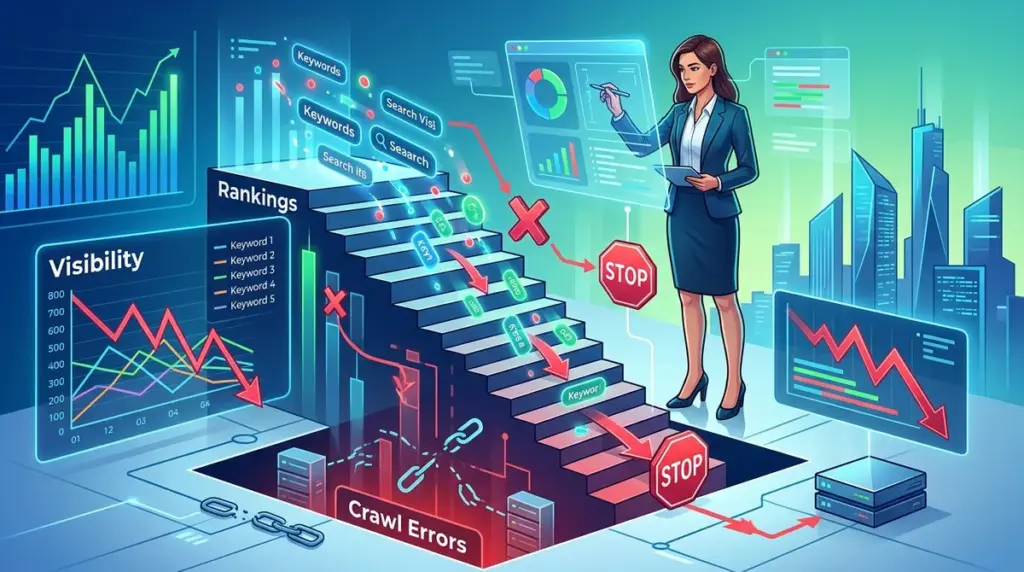
SEO visibility is binary: either a search engine can access, parse, and index your content, or it cannot. While content strategy and backlink profiles often dominate the conversation, crawl errors represent a fundamental failure in the technical handshake between your server and search engine bots. When Googlebot encounters a wall—whether it is a 500-series server error or a messy redirect loop—it does not just skip that page; it begins to devalue the entire directory or domain based on perceived unreliability. For site owners, these errors translate directly into lost rankings, as search engines prioritize stable, accessible URLs to protect the user experience.
The Direct Impact of Crawl Errors on Indexation
A crawl error occurs when a search engine attempts to reach a page on your site but fails. This failure typically falls into two categories: site errors and URL errors. Site errors are systemic, often involving DNS issues or server connectivity problems that prevent the bot from even reaching the domain. URL errors are specific to individual pages. In both cases, the immediate result is the removal of the affected URLs from the index. If a page is not in the index, it cannot rank, regardless of how optimized the on-page copy might be.
When a bot repeatedly fails to crawl a page, Google eventually interprets the page as non-existent or permanently broken. This triggers a removal of the page’s historical data from the ranking algorithm. Even after the error is fixed, there is often a significant lag before the page regains its previous positions, as the bot must re-discover, re-crawl, and re-evaluate the content’s relevance from scratch.
Critical Error Types That Trigger Ranking Volatility
Not all crawl errors are treated with the same level of urgency by search engines, but several specific status codes are notorious for causing rapid ranking declines.
404 Errors and the Loss of Link Equity
A standard 404 (Not Found) error tells the bot that the page is gone. While 404s are a natural part of the web, they become a ranking liability when they occur on pages that previously held significant backlink equity. When a high-authority page returns a 404, the "link juice" flowing from external sites hits a dead end. This equity is effectively deleted from your site’s total authority calculation. If you do not 301 redirect these pages to a relevant alternative, you are essentially throwing away the ranking power those links provided.
Soft 404s: The Deceptive Ranking Killer
A "Soft 404" occurs when a page tells the user it doesn't exist (displaying a "Page Not Found" message) but returns a 200 OK status code to the search engine. This is particularly damaging because it confuses the crawler. Googlebot sees a 200 OK and expects a high-quality page, but instead finds thin or irrelevant content. Over time, a high volume of Soft 404s signals to Google that the site is poorly maintained, leading to a site-wide "quality" demotion in the search results.
5xx Server Errors and Reliability Signals
500 (Internal Server Error) and 503 (Service Unavailable) codes are the most dangerous for rankings. These indicate that your server is unable to handle the request. If Googlebot encounters frequent 5xx errors, it will slow down its crawl rate to avoid crashing your server. This reduction in crawl frequency means new content takes longer to index and updates to existing content are not reflected in the SERPs, leading to stagnant or declining rankings.
Warning: Frequent 503 errors can lead to Google temporarily dropping your entire site from the search results. Google views a persistent 503 as a sign that the site is not ready for public traffic, and it will prioritize "healthier" competitors to ensure users aren't clicking on broken links.
The Erosion of Crawl Budget on Enterprise Sites
For sites with thousands or millions of pages, "crawl budget" is a finite resource. This is the number of pages Googlebot can and will crawl during a specific timeframe. Crawl errors are a massive drain on this budget. When a bot spends its time hitting 404s, redirect chains, or blocked parameters, it is not spending time on your revenue-generating product pages or new blog posts.
- Redirect Loops: If Page A points to Page B, and Page B points back to Page A, the bot gets stuck. This wastes crawl budget and prevents the bot from moving deeper into your site architecture.
- Infinite Spaces: Dynamically generated URLs (like calendar filters or excessive search facets) can create an infinite number of crawlable paths that lead to thin content or errors, effectively "drowning" the bot.
- Robots.txt Blockages: Accidentally blocking important CSS or JS files can lead to "partial" crawl errors where Google cannot see the rendered version of your site, leading to a failure in Mobile-First Indexing checks.
Identifying and Resolving Crawl Bottlenecks
To prevent ranking losses, technical audits must move beyond surface-level checks. You need to look at how the bot interacts with your infrastructure in real-time. This requires a combination of Google Search Console data and server-side log analysis.
Log File Analysis for Deep Insights
While tools like Search Console provide a summary, log files show the raw truth. By analyzing your server logs, you can see exactly when Googlebot visited, which status code it received, and how much data it downloaded. This allows you to spot "zombie" pages—URLs that are being crawled despite being useless—and identify 5xx errors that may only occur during peak traffic hours when the bot is most active.
Auditing Internal Link Architecture
Internal links are the roadmap for crawlers. If your internal links point to 404 pages or through multiple 301 redirects, you are creating friction. A clean site architecture uses direct 200 OK links for all primary navigation and internal content. Reducing the number of "hops" a bot must take to reach a page increases the likelihood of that page being indexed and ranked highly.
Best for: Large e-commerce sites and publishers who frequently update or delete content. Regular automated scanning of internal links ensures that the "crawl path" remains clear of obstacles.
Developing a Proactive Crawl Maintenance Strategy
Ranking stability is not a one-time achievement; it is the result of continuous technical hygiene. To protect your organic traffic, you must treat crawl errors as high-priority bugs rather than minor maintenance tasks. Start by setting up weekly alerts in Google Search Console for "Crawl Stats" and "Index Coverage." If you see a spike in "Excluded" pages or server errors, investigate the root cause immediately—whether it is a faulty plugin, a misconfigured .htaccess file, or a server capacity issue.
Furthermore, ensure that your XML sitemap is dynamically updated to only include 200 OK URLs. Submitting a sitemap full of redirects or 404s is a fast way to lose the "trust" of the crawler. By maintaining a 1:1 ratio between the URLs you want to rank and the URLs the bot can successfully crawl, you create a streamlined environment where your content can perform at its maximum potential.
Frequently Asked Questions
How long does it take to recover rankings after fixing crawl errors?
Recovery time varies based on crawl frequency. For high-authority sites, it may take a few days. For smaller sites, it can take several weeks for Googlebot to re-crawl the fixed URLs and update the index. Using the "URL Inspection Tool" in Google Search Console to manually request indexing can speed up this process for critical pages.
Do 404 errors on my site hurt the rankings of other pages?
Generally, a few 404s won't tank your entire site. However, if a significant percentage of your internal links point to 404s, it creates a poor user experience and a "low quality" signal for the site as a whole. This can indirectly suppress the ranking potential of your healthy pages.
What is the difference between a 301 and a 302 redirect for crawling?
A 301 redirect is permanent and passes the majority of ranking power (link equity) to the new URL. A 302 is temporary and tells the bot to keep the old URL in the index. Using a 302 when you mean to move a page permanently can lead to "canonicalization" issues where the wrong page shows up in search results.
Can a slow server cause crawl errors?
Yes. If your server takes too long to respond, the crawler may time out. Googlebot interprets these timeouts as "Connection Failed" errors. Even if the page eventually loads for a human user, the bot may have already moved on, leading to a failure to index or a drop in ranking due to poor "Core Web Vitals" and reliability scores. This is why it's vital to track rankings to validate technical SEO fixes, ensuring improvements are reflected in search results.