Data integrity in rank tracking is not a luxury; it is the foundation of every SEO budget allocation and performance report. When a rank tracker provides a position, it is the result of a complex, multi-stage technical handshake between specialized software and search engine data centers. For agencies and enterprise marketers, understanding this "black box" is essential for troubleshooting discrepancies and ensuring that the data used to justify high-stakes decisions is actually representative of the live market.
The Infrastructure of Data Retrieval: Proxies and Request Management
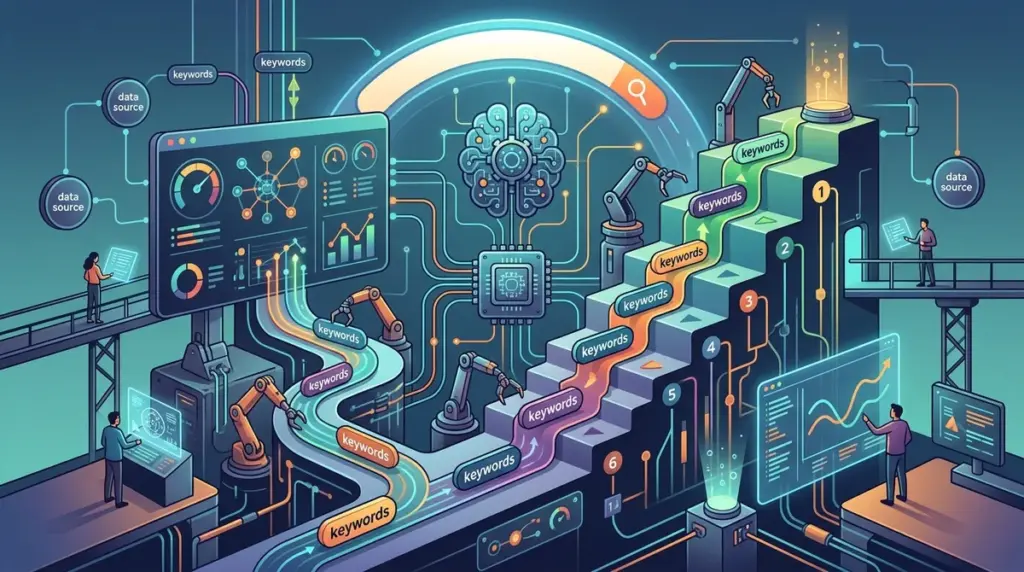
At its core, a rank tracker is a sophisticated crawler. However, unlike a standard search engine bot that moves from link to link, a rank tracker must simulate a specific user in a specific location on a specific device. To do this without being blocked by anti-scraping mechanisms, trackers utilize vast networks of proxies.
Datacenter vs. Residential Proxies: Most entry-level tools rely on datacenter proxies because they are cost-effective and fast. However, search engines easily identify these IP ranges. High-tier trackers use residential or mobile proxies, which route requests through real consumer internet connections. This makes the request indistinguishable from a genuine user search, significantly reducing the risk of being served "CAPTCHAs" or distorted data.
- Request Throttling: Trackers must pace their queries to avoid triggering rate limits.
- User-Agent Spoofing: The system sends headers that tell the search engine whether it is a Chrome browser on an iPhone 15 or a Firefox instance on a Windows desktop.
- IP Rotation: To prevent pattern recognition, trackers cycle through thousands of IPs across different geographic regions.
Parsing the Document Object Model (DOM) and SERP Features
Once the tracker successfully fetches the HTML of a search engine results page (SERP), the real work begins. Modern search results are no longer just "ten blue links." They are a dense collection of JavaScript-heavy elements, including Local Packs, People Also Ask (PAA) boxes, Featured Snippets, and AI Overviews.
The tracker uses a parser to scan the Document Object Model (DOM). It identifies specific CSS classes and HTML IDs to categorize each result. For instance, a link found within a specific <div> container might be flagged as a "Sponsored" result, while another is identified as a "Video Carousel" entry. This level of granularity is what allows SEOs to track "Share of Voice" rather than just a raw numerical position.
Warning: Be wary of trackers that only provide raw HTML snapshots. Without a headless browser—a browser without a graphical user interface—the tracker may fail to trigger the JavaScript required to render modern SERP features, leading to underreported visibility for your most valuable keywords.
Localization and the Role of GPS Emulation
Search results are hyper-local. A search for "commercial insurance" in New York yields different results than the same search in London, or even in a different zip code within the same city. To capture this, trackers use two primary methods: IP-based geolocation and the uule parameter.
The uule parameter is a base64-encoded string that Google uses to transmit specific location data, down to the neighborhood level. Advanced trackers generate these strings to "teleport" the crawler to a specific coordinate. This is critical for local SEO campaigns where the "Map Pack" ranking is the primary KPI. If your tracker isn't using precise GPS coordinates or uule parameters, the data you are seeing is likely a "national average" that bears little resemblance to what local customers actually see.
Data Normalization and Storage Latency
After the data is parsed, it must be normalized. A rank tracker doesn't just store a screenshot; it converts the SERP into a structured format, usually JSON. This data includes the URL, the title tag, the meta description, the presence of schema markup, and the "pixel height" of the result.
Pixel Tracking vs. Traditional Ranking: Many professional-grade tools now track the number of pixels from the top of the page to the first organic result. This is a more commercially useful metric than "Position 1," because a Featured Snippet and a massive ad block can push the first organic result 1,200 pixels down the page, effectively making it invisible to the user despite its "top" ranking.
The frequency of this data collection—whether it is daily, hourly, or on-demand—determines the "freshness" of your dashboard. High-volatility industries, such as news or e-commerce during Black Friday, require on-demand refreshes to capture rapid SERP shifts that occur during algorithm updates.
Optimizing Your Tracking Strategy
To get the most out of your rank tracking infrastructure, you must align the tool’s technical capabilities with your business goals. If you are managing a global brand, you need a tracker with a massive proxy network across multiple continents. If you are a local service provider, your priority is uule accuracy and Map Pack tracking.
Regularly audit your tracker by comparing its "cached" view of the SERP against a manual search performed in a clean, incognito browser with localized settings. If the discrepancies are consistent, it is a sign that the tracker's proxy network is being flagged or its parsing engine is outdated. Reliable data is the only way to prove SEO value to stakeholders; ensure your technical foundation is capable of delivering it.
Frequently Asked Questions
Why do my rankings look different when I check them manually?
Manual searches are influenced by your personal search history, cookies, and your specific IP address. Even in incognito mode, search engines use your ISP's location. Rank trackers use clean proxies and specific location parameters (like uule) to provide a "neutral" result that reflects what a new user in that specific area would see.
What is the difference between daily and on-demand tracking?
Daily tracking takes a snapshot at a set time every 24 hours, which is sufficient for monitoring long-term trends. On-demand tracking allows you to trigger a fresh crawl immediately. This is essential during site migrations, major content updates, or when a search engine rolls out a core algorithm update and you need real-time feedback.
Does rank tracking software affect my website's server performance?
No. Rank trackers do not crawl your website; they crawl the search engine's results pages. Unlike site auditors (like Screaming Frog) that hit your server directly, a rank tracker interacts only with the search engine. Your site's performance remains unaffected regardless of how many keywords you track. To truly grasp this, it's helpful to understand what a rank tracker is and why it matters for your online visibility.
Can search engines tell I am using a rank tracker?
Search engines have sophisticated systems to detect automated traffic. However, high-quality trackers use residential proxies and human-like browsing patterns to remain undetected. If a tracker is detected, the search engine typically blocks the proxy IP or serves a CAPTCHA, rather than penalizing the website being tracked.